DevOps foundations for teams running cloud and AI products
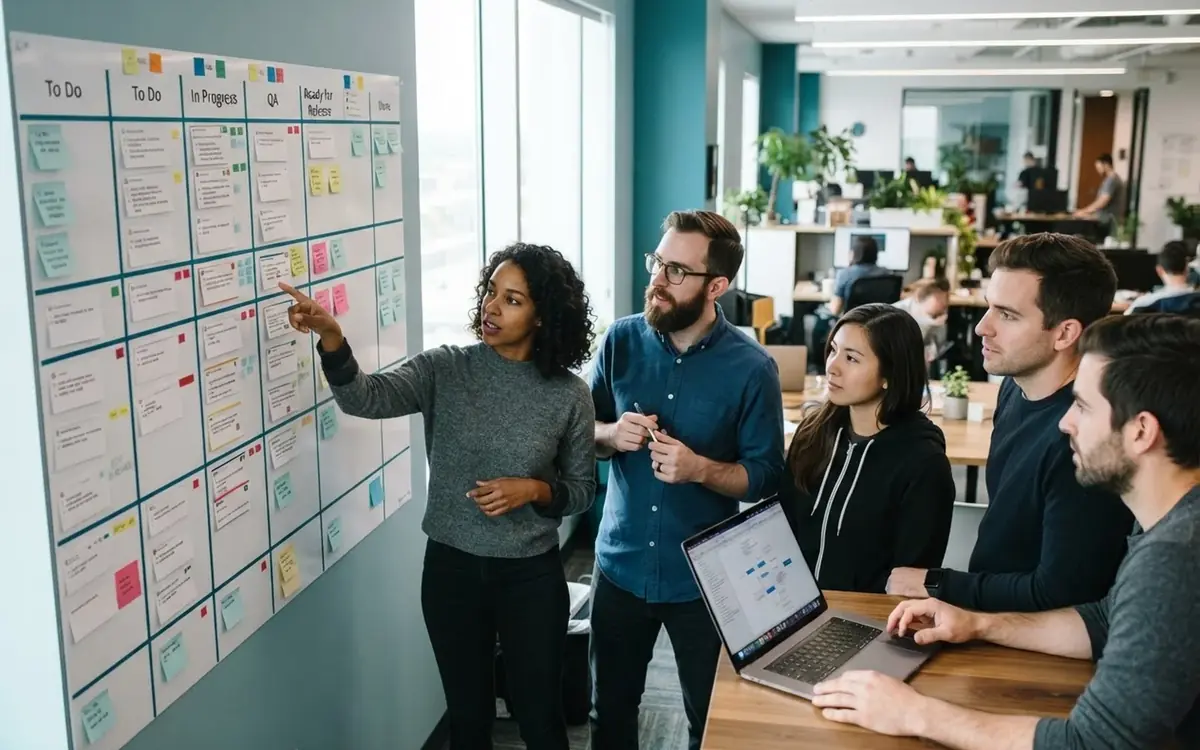
Not only the infrastructure but the pipelines, dashboards and alert rules live in Git, so a change to an alert threshold gets the same review as a change to the code, and nothing on the platform exists only because someone clicked it. Pipelines run the same stages for every service: build, unit tests, dependency and container scanning, deployment to an ephemeral environment for integration tests, then a staged release, and a service that cannot pass those stages is not yet ready to be operated. For AI products the artefacts are different: model weights and training data are too large for Git, so an artefact store and model registry sit beside the code repository, and a release pins a specific model version as deliberately as a specific commit. Evaluation steps run on GPU runners, which standard CI agents lack.
How models are deployed, served and rolled back in production
A model goes to production in a container that pins the runtime, the weights and the pre-processing code together, because a mismatch between the three is a common cause of a model that scored well offline and misbehaves live. The first release of a new version is usually a shadow deployment: it receives a copy of real traffic, its answers are logged and compared with the current model, and nothing it says reaches a user. Then a small percentage of live requests, then the rest. Rollback is a pointer back to the previous registry version, not a rebuild. Observability for serving covers four axes: 95th-percentile latency, throughput, the distribution of inputs against the training data, and accuracy once ground truth arrives. GPU nodes autoscale on queue depth rather than CPU, and cost is reported per thousand inferences.
Reliability engineering, on-call and cost control after launch
Reliability is defined before it is monitored. Each service gets a service-level objective in terms a product owner understands, such as the share of requests answered within a second, and an error budget that decides whether the next sprint ships features or fixes. Alerts page a human only for symptoms that spend that budget; everything else opens a ticket. Automated rollback is wired to the same signals, so a release that raises the error rate reverses itself before anyone reads the page. Incidents follow a written process with a timeline and a blameless review whose actions enter the backlog, and rollback is rehearsed on a quiet afternoon rather than discovered during an outage. On the cost side, training runs on spot capacity, idle GPU environments scale to zero overnight, and the monthly bill is split per service and model.