GLOBAL DELIVERY · LHR / SYD / RUH / KHI
Book a Free ConsultationExplore Careers
Theme
AI & Data Solutions

Data Engineering & Big Data Strategy

We build the data pipelines, lakes, and warehouses that turn raw, scattered data into something your business can actually use.

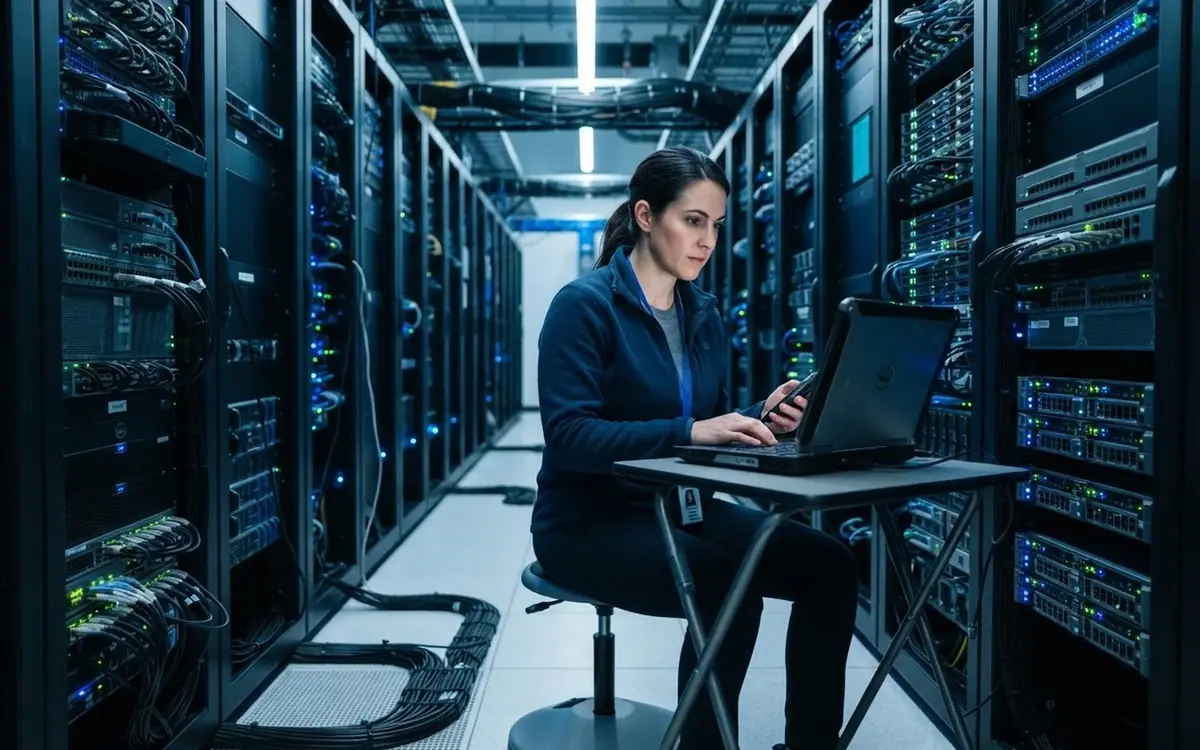
A data engineer checking a laptop in a data centre aisle
AI & Data Solutions

What we deliver

Most teams are not short on data, they are short on data they can trust and reach. DevelMo designs and builds the engineering layer underneath your analytics and AI: automated pipelines, governed warehouses and lakes, and real-time streams that keep clean, structured data flowing to the people and models that need it. Cloud or on-premise, built to scale as your volumes grow.

At a glance
Platforms
Snowflake, BigQuery, Redshift, Databricks
Pipelines
Batch, streaming, ELT with dbt
Deployment
Cloud, on-premise or hybrid
Governance
Lineage, quality checks, access policies
  • Design and build automated data pipelines that move, validate, and reconcile data between source systems with no manual intervention

  • Engineer ETL and ELT workflows that extract from databases, APIs, and files, transform to a clean model, and load into your analytics layer

  • Stand up data lakes and warehouses that centralise structured and unstructured data into one queryable source of truth

  • Build real-time streaming pipelines for fraud signals, live operational dashboards, and event-driven processing

  • Define a big data strategy: target architecture, tooling choices, and a phased roadmap aligned to your business goals

  • Implement data governance and quality controls including schema validation, lineage, access policies, and compliance handling

  • Model and warehouse data for BI and machine learning so analysts and models consume trusted, well-shaped tables

  • Migrate legacy data stacks and spreadsheets into modern cloud platforms with minimal downtime

Technology

Models, data platforms and tooling

How we work

From your data to a model in production

  1. Audit sources and uses

    Every system that produces data, every team that needs it and the quality of what flows between them, assessed in the first two weeks.

  2. Target architecture

    Warehouse or lake, streaming where it pays, tooling choices and a phased roadmap tied to the analytics and AI you want from it.

  3. Build the pipelines

    Automated, tested, monitored pipelines that move, validate and model data, delivered source by source with the consumers using each as it lands.

  4. Govern and hand over

    Lineage, access policies, quality alerts and documentation, with your team trained to run and extend the platform.

What you get

Outcomes

01

One source of truth

We consolidate scattered systems into a governed warehouse or lake, so reporting, analytics, and AI all draw from the same clean, reconciled data instead of conflicting exports.

02

Decisions on fresh data

Automated and streaming pipelines replace overnight batch jobs and manual updates, so dashboards and models reflect what is happening now, not what happened last week.

03

An architecture that scales

Pipelines and storage are built to absorb growth in volume and new sources without re-engineering, so the platform keeps pace as your data and your team expand.

Why DevelMo

Why teams choose DevelMo for this

01

Foundations for the AI that follows

We build the data layer with the models and dashboards that will consume it in mind, so analytics and machine learning move faster afterwards.

02

Pragmatic about tooling

Snowflake, BigQuery, Redshift, Databricks or Postgres: we choose for your volumes, team and budget, and we say when something simpler will do.

03

Quality you can see

Schema checks, freshness alerts and lineage make a broken feed visible in minutes, not in a board meeting.

Where it shows up

Industries where we do this

In depth

Beyond the demo

Data pipelines and warehouses engineered as one trusted layer

The layer we build sits between your source systems and everyone who needs answers from them. Ingestion comes first, pulling from databases through change data capture, from SaaS tools through their APIs and from file drops partners still send, and landing everything raw and unaltered so nothing is lost if a transformation later proves wrong. Transformation happens inside the warehouse with dbt, where every model is code in version control, reviewed like any other software and covered by tests that run on each execution. Airflow orchestrates the dependencies and retries, Spark handles the volumes a single machine cannot, and Kafka carries the events that cannot wait for a scheduled run. The result is a set of documented, consistently modelled tables that a dashboard, a finance analyst and a machine-learning feature store all read in the same way.

Choosing between warehouse, lake, streaming and on-premise before building

Three questions decide most of a big data strategy. The first is how fresh the data needs to be. Streaming through Kafka costs more to build and operate than a pipeline that runs every fifteen minutes, so we reserve it for fraud signals, stock positions and operational screens where a quarter of an hour is too long. The second is where the data may live. Residency rules, contractual clauses and the location of your largest source systems can rule out a cloud warehouse or force a hybrid in which raw records stay on-premise and only aggregates leave. The third is who will run it. A lean team is better served by a managed warehouse than by a Spark cluster, even when the cluster looks cheaper per query. The roadmap sequences the answers so each phase hands a consumer something usable.

Data governance, quality checks and handover that keep the platform running

Governance only holds if it runs automatically, so we express it as tests and policies in the same repositories as the pipelines. Every dbt model carries assertions on uniqueness, nulls, accepted values and referential integrity, and a failing assertion stops the load before bad rows reach a table anyone reads. Freshness checks compare each source's latest timestamp against its agreed cadence and page the owner when a feed goes quiet. Lineage is generated from the transformation code itself, so when a column changes you can see every dashboard and model downstream before deploying. Access policies are applied at the warehouse layer, with row and column restrictions for personal or commercial data. At handover you hold the code, the documentation and the monitoring, with no proprietary layer between you and your data and nothing that stops if we step away.
FAQ

Common questions

Do you work with cloud, on-premise, or both?

Both. We design around your constraints, whether that means a fully cloud-native stack on Snowflake, BigQuery, or Redshift, an on-premise deployment for data-residency or compliance reasons, or a hybrid of the two.

We already have data, it is just a mess. Where do you start?

With an audit of your current sources, quality, and use cases, followed by a target architecture and a phased roadmap. Early stages usually focus on cleaning and governing the data you have before adding new pipelines or real-time processing.

How does this connect to analytics and AI?

Data engineering is the foundation both depend on. We model and warehouse your data so BI tools and machine-learning models consume trusted, well-structured tables, which makes downstream analytics and computer-vision or AI work faster and far more reliable.

Let's build AI that fits your business

Talk to an engineer who has shipped this, not a salesperson. Free 30-minute consultation.

Let's Talk